Reasoning effort: the setting that decides your AI bill
One lab gives you six levels from none to max. Another runs adaptive thinking with a default effort. A third calls it configurable. Left alone, a model thinks as hard as it is allowed — and we watched that turn a five-second job into a hundred and seventy.
There is a control on every current frontier model that almost nobody touches, and it moves latency and cost more than the choice of model does.
It has a different name at each lab, which is part of why it gets missed.
What each one exposes
Read off the labs' own docs on 25 September 2026. We call them A, B and C and leave the model names out — they change, and the control does not.
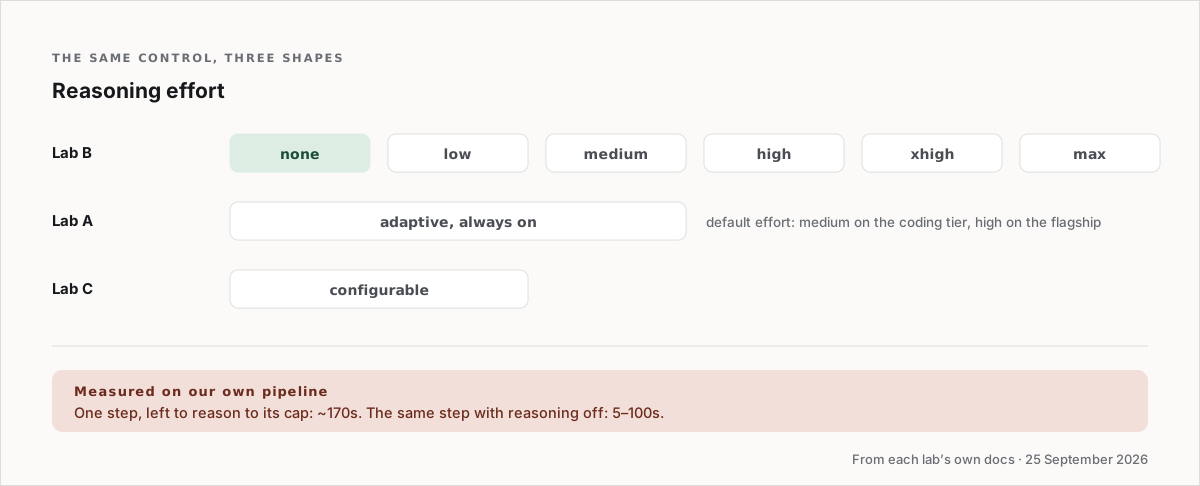
Lab B puts a reasoning level on every model in its line: none, low, medium, high, xhigh, max. Six positions, and the first one is off. Its flagship offers five of them, starting at low.
Lab A describes thinking on its flagship and its coding tier as adaptive and always on, each with a default effort — medium on the coding tier, high on the flagship. Its mid tier is adaptive. Its small tier uses extended thinking rather than the adaptive setting.
Lab C describes its reasoning as configurable, and always returns encrypted reasoning content on its Responses API whether or not you ask for it.
Why it matters more than it sounds
Thinking tokens are output tokens. Output is billed at five times input at two of these labs, and three times at the third. A model that reasons for two thousand tokens before writing a two-hundred-token answer has just charged you for eleven times the answer.
And the reasoning is not free in time either, which is the part users feel.
What we measured
We hit this on DragGo's own build pipeline while testing a cheaper tier of models.
The symptom was that a step which should have been quick was taking about 170 seconds, consistently. Nothing was broken. The model was doing exactly what it had been left free to do: reason to its cap on a task that did not need it.
Setting reasoning explicitly off for that call brought the same step down to between five and a hundred seconds depending on the input. Same model. Same prompt. Same output quality for that particular job, which was a simple structured one.
The lesson was not "turn reasoning off". It was that the default is a guess, and the guess is generous. A model with no instruction about how hard a problem is will assume it is hard.
A rule of thumb that has held up
Match the effort to the shape of the task, not to how much you care about the result:
- Off or low — anything with a fixed shape. Extracting fields, writing alt text, formatting, classification, choosing from a short list. The answer is looked up, not worked out.
- Medium — most real work. Writing a section of copy, summarising a document, a single well-specified code change.
- High and above — genuinely open problems. Planning something multi-step, debugging from a symptom, anything where the first plausible answer is often wrong.
The mistake to avoid is treating effort as a quality dial. It is not "try harder". It is "this problem has more than one path and you should look at a few". On a task with one path, extra effort buys you latency and nothing else.
Effort matched to the task. Which is why a DragGo page arrives in seconds instead of behind a progress animation. Try DragGo free.
The thing to check in your own code
Two failure modes, both quiet:
You never set it. Every call runs at the lab's default. On Lab A's flagship that default is high. You are paying frontier reasoning prices on jobs that are formatting.
You set it and it is being ignored. Worth reading the docs for the exact model you are on. Lab C's, for example, note that logprobs and top_logprobs are silently ignored on its newer models — a parameter accepted and discarded rather than rejected. That class of thing is discovered from a bill, not from an error.
The five minutes it takes to print the effort setting alongside the latency of each call in your logs is the cheapest observability you will ever add.
If you are choosing between models rather than tuning one, here is how to compare them.