What actually happens when an AI builds a web page
Not one prompt to one model. A page build is seven separate jobs, and only one of them is worth the strongest model available. This is our own router, described job by job, including the bug that was sending half of our smallest edits to the most expensive model.
Search for how an AI website builder works and you get the same shape of answer everywhere: you describe what you want, it generates a site, you edit it. That is true and it is also not an explanation. It is the outside of the box.
This is the inside of ours. Not because our way is the only way, but because almost nobody publishes this, and the useful questions about AI builders — is it any good, why does it sometimes produce something bland, what does it cost to run — all have answers that live at this level.
It is not one prompt
The mental model most people carry is one long prompt going to one large model, which returns a website. If that were how it worked, every page would cost the same and every page would be as good as the model's best day.
A page build in our editor is seven separate calls, and which model answers is decided per call, by the job. That is the single most important design decision in the whole thing, and everything below follows from it.
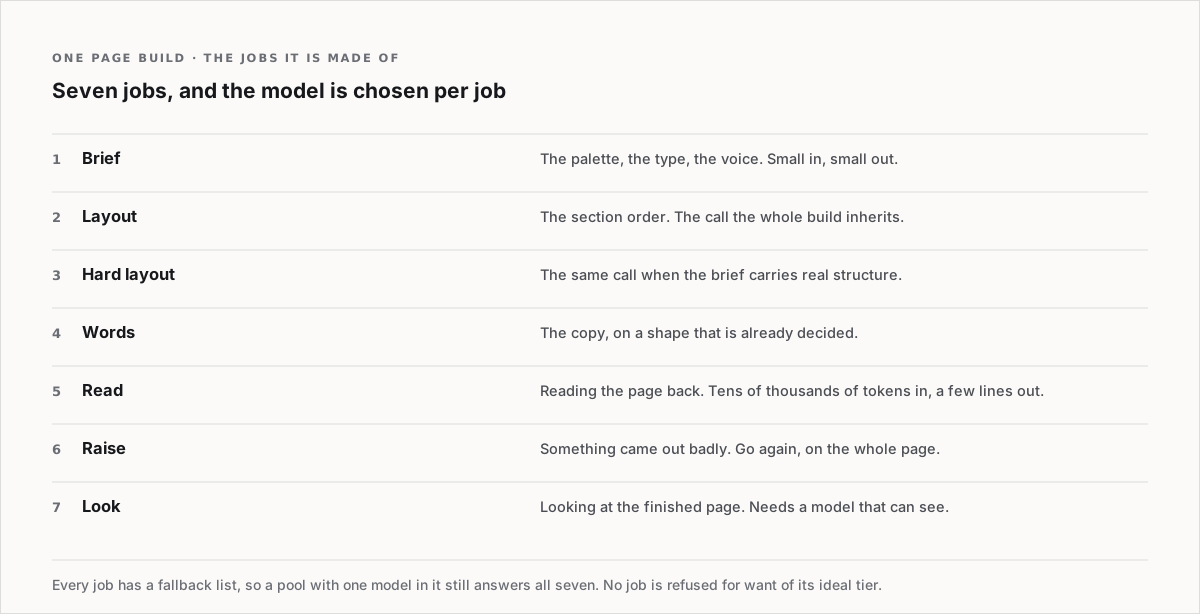
The jobs are named for the work rather than for the model, which is not a stylistic choice — it is what makes the next decision possible.
Only one of them deserves the strongest model
Most of a page does not need a reasoning model, and paying for one everywhere is how AI features become expensive without becoming better.
The brief call decides the palette, the typefaces and the voice. Small input, small output, and the structure it produces is fixed by our engine rather than by the model — so a quick model does it well. The words call writes the copy, and a cheap model writes a perfectly good sentence. What a cheap model cannot be trusted with is the shape of a page, and by the time the words are written the shape is already decided.
The one call worth paying for is the arrangement — and only when the brief actually carries structure. Our test for that is narrow and deliberate, because "this brief is hard" has to mean something. It is hard when:
- it is more than one page, or involves a CMS
- it names a design system, style guide, brand guidelines or component library
- it asks for a mechanism: booking, checkout, cart, a calculator, a configurator, a dashboard, a portal, a multi-step form
- it asks for a collection: a blog, a catalogue, an inventory, listings, a directory
- it is bilingual, or right-to-left
Everything on that list is structure the arrangement has to hold. None of it is a matter of taste, because taste is the brief call's job, and a light model does taste well.
Where the saving actually is
The job nobody expects to matter is read — the one that reads the page back. Edit operations, the responsive pass, the finish pass: tens of thousands of tokens of page going in, a handful of lines coming out.
That shape, huge input and tiny output, is the cheapest kind of work there is if you send it to a model built for long input instead of to a reasoning model. Almost all of the saving in the entire system lives in that one job. It is also the least glamorous thing in this article, which is probably why it is missing from everyone's explanation.
What happens when a page comes out badly
Sometimes it does. A reply that cannot be used, a repair that did not take, a finished page that measures badly against our own checks.
The cheap instinct is to patch the section that failed. We do the opposite.
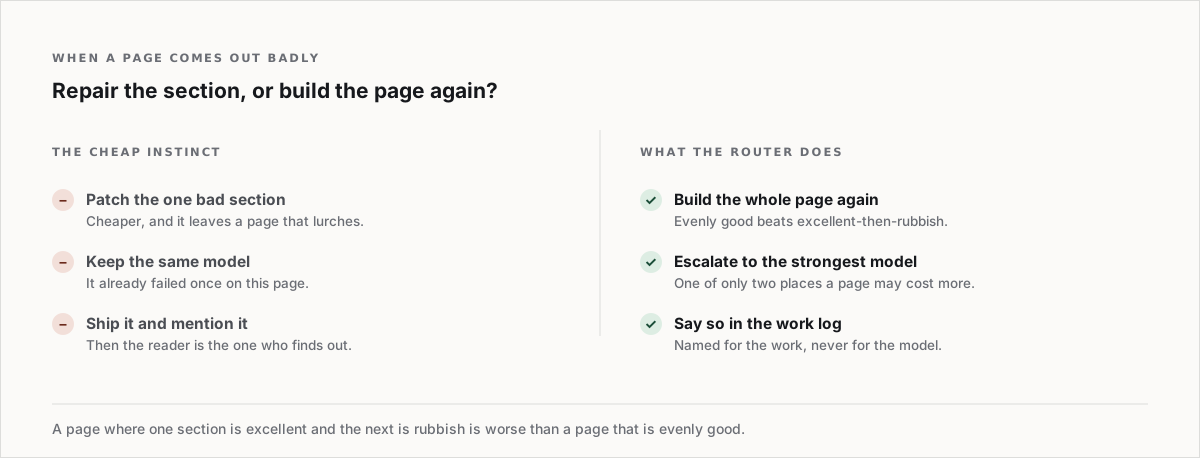
The escalation is always asked for the whole page, never for one band, and the reason is a design judgement rather than an engineering one: a page where one section is excellent and the next is rubbish is worse than a page that is evenly good. Patching produces the first. Rebuilding produces the second.
It is also one of only two places where a page is allowed to cost more than usual. Everything else in the system is built to spend less.
The bug that made half our small edits expensive
This is the part that is embarrassing and worth publishing anyway.
A small edit — one property, one line of copy, one element you have already selected — should go to the cheapest model the account can use. There is a gate that recognises those requests, and it works off a list of words.
The list had the word "colour" in it. It did not have any colour names. So "make this blue" did not look like a small edit, and neither did red, green, uppercase, shadow, wider or shorten. Measured over twenty realistic selection-scoped edits, ten of them walked straight past the gate and were answered by the reasoning model. Nine died on that word list; one died a line earlier.
The fix was to add the names, which took minutes. The lesson took longer: nobody says the word "colour" when they mean blue, and a gate written in the vocabulary of the code rather than the vocabulary of the user will always leak in exactly this way.
The gate is deliberately biased, too. It errs toward not calling something small. Guessing cheap means a page-shaping decision made by the weakest model on the account, which is the failure the whole product exists to prevent. Guessing expensive just costs what it costs that day. Those two mistakes are not the same size, so the gate is not symmetrical.
Why we do not tell you which model answered
A fair question, and the honest answer is a consequence of everything above rather than a policy.
The model is chosen per call. A single page is built by three or four of them. So there is no one name that would be true while the build is running, and a control offering you a choice between two model names would be asking you to decide something on no information. What you choose is free or paid; the job decides the rest, and the work log tells you what each call was for — the arrangement, the writing, reading the page back — which is the part you can actually act on.
One more thing follows from the routing being this mechanical: it is pure. The same inputs route the same way every time, so the whole thing is covered by a unit test that never touches the network. A router you cannot test is a router that quietly gets more expensive.
See what it intends, before it builds it. One approval card: the real palette, the sections it will use, and what each call is for. Browse the Market.
What to ask any AI builder
You will not get a router diagram out of most of them, but you can get at the same information sideways:
- Does the price change with the request? A flat price per page usually means one model for everything, which means either bland pages or an unsustainable bill.
- Can it work on the page you already have? Generating a new site and editing an existing one are genuinely different problems, and several builders only do the first.
- What does it do when it fails? "It tries again" is the interesting answer. Ask what it tries again on.
- Can it see the finished page? A builder that never looks at its own output is guessing about the thing you will actually look at.
- What comes out at the end? A file you own, or a page that has to keep running on their servers.
The generating is the easy half now. What separates one AI builder from another is the boring machinery around the generating — and that is worth asking about, because it is the part that decides whether the second page is as good as the first.